Kimi K3.1 Pro: the $2 AI that beat Claude Opus on a coding test
Published Oct 24, 2026
Moonshot AI's new model scores close to the top for about a third of what Claude Opus costs per task, and it set the record on Terminal-Bench.
Moonshot AI, a lab in Beijing, released Kimi K3.1 Pro on Oct 23. The same day, Artificial Analysis, an independent group that runs every AI model through the same set of hard tests, gave it 55.1 on their Intelligence Index. That's their overall score for how smart a model is, and it put Kimi third of the 21 current models on our chart. One test task cost $2.12 to run, on average.
Of the models you can pay for by the task, only two score higher: Claude Opus 5.5 and Claude Sonnet 5.5. Each costs between 2.5 and 3 times as much per task.
If you're just starting out with Claude Code or Codex, nothing changes for you: they use their own company's models. The price matters later, once you build something that asks an AI a question every time someone uses it. More on that under "What it means if you build with AI" below.
The chart
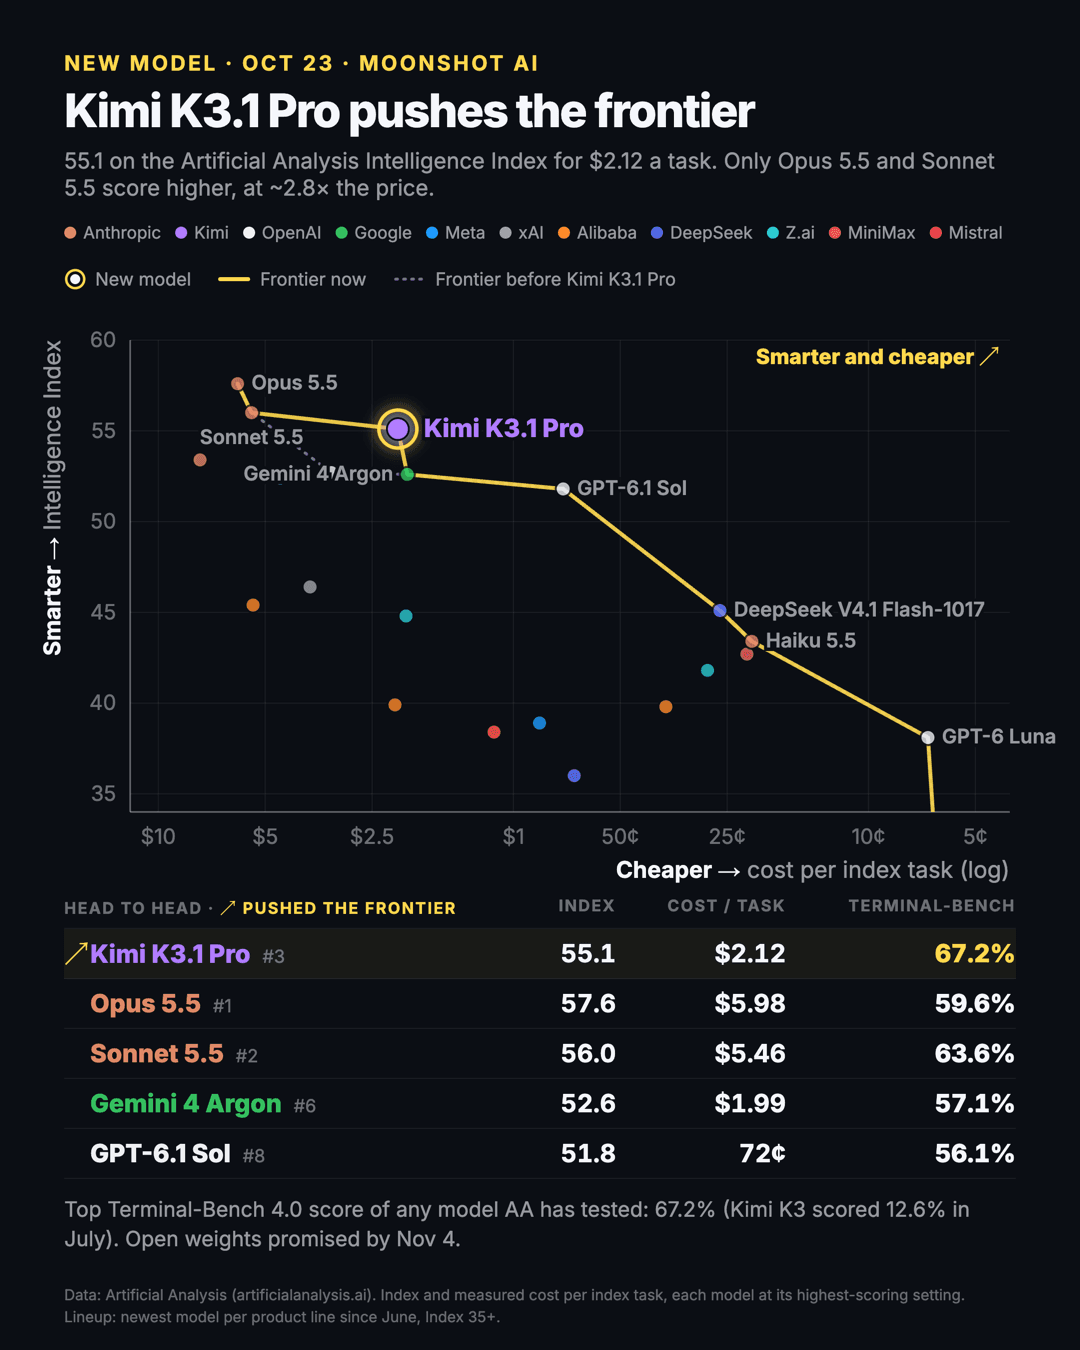
The dotted line shows the best you could buy before Kimi. It ran straight from Sonnet 5.5 down to Gemini 4 Argon. Kimi landed above that line, and no model beats it on both score and price, so the yellow line now bends out to include it. That line is the frontier: the models that nothing else beats on both score and price.
| Model | Intelligence Index | Cost per task |
|---|---|---|
| Kimi K3.1 Pro | 55.1 | $2.12 |
| Claude Opus 5.5 | 57.6 | $5.98 |
| Claude Sonnet 5.5 | 56.0 | $5.46 |
| Gemini 4 Argon | 52.6 | $1.99 |
| GPT-6.1 Sol | 51.8 | $0.72 |
The coding test
Terminal-Bench 4.0 hands a model real jobs to finish in a terminal, the plain text window programmers type commands into, then checks whether each job actually got done. Kimi K3.1 Pro finished 67.2% of them. No model Artificial Analysis has tested scores higher.
| Model | Terminal-Bench 4.0 |
|---|---|
| Kimi K3.1 Pro | 67.2% |
| Claude Sonnet 5.5 | 63.6% |
| Claude Opus 5.5 | 59.6% |
| Gemini 4 Argon | 57.1% |
| GPT-6.1 Sol | 56.1% |
The Kimi before it, K3, scored 12.6% on the same test in July.
What it means if you build with AI
If you build with Claude Code or Codex, nothing changes today. Those tools use their own company's models.
The price matters once you build something that asks an AI model a question every time someone uses it, like the costume idea generator. Each of those questions is a task you pay for. A model that scores near the top for about a third of Opus's price makes that kind of project cheaper to run.
Moonshot also says it will release the model's weights by Nov 4. The weights are the trained model itself. Once they're out, anyone can download Kimi K3.1 Pro and run it on their own hardware instead of paying per task.
Where the name comes from
Moonshot's Chinese name, 月之暗面, means "The Dark Side of the Moon", after the Pink Floyd album. The company launched in March 2023, the month the album turned 50.
New to all this?
Vibe coding means describing what you want in plain English while an AI writes the code. Start with what vibe coding is, then install Claude Code and build your first page.
Sources
- Scores, prices and Terminal-Bench results: Artificial Analysis, pulled Oct 23, 2026. Each model is measured at its highest-scoring setting.
- Release date and the Nov 4 open-weights promise: Moonshot AI's announcement, as reported by Artificial Analysis.
- The name and founding date: Wikipedia.
Get new guides and videos by email
One email when something new is up. No spam. Unsubscribe anytime.